The High Performance Computing course develops a structured understanding of parallel and accelerated computing through eight source-defined units. The curriculum begins with HPC foundations and architecture, hardware and local lab setup before moving into parallel-computing fundamentals. Learners then progress through distributed-memory programming with MPI, shared-memory programming with OpenMP and GPU computing with CUDA.
Later units connect programming with local HPC operations, including SLURM, storage, containers and a Proxmox lab, before concluding with performance optimization and capstone workflows. Every unit combines theory sessions with hands-on sessions, creating a consistent path from concepts to practical activity. The course is designed for technical learners and professionals who want a source-aligned introduction to HPC programming, operations and optimization in an online six-week format.
Develop parallel computing skills across CPU, GPU and cluster workflows
This opening module establishes the source-defined foundations of high performance computing. Learners first build conceptual context through the theory session and then reinforce the unit through a hands-on session. The module prepares the learning path for architecture, parallel-computing models, accelerated computing, local HPC operations and performance optimization covered in later units.
This module focuses on the architecture, hardware and local lab setup named in the source curriculum. The theory session develops understanding of the environment in which HPC workloads operate, while the hands-on session connects that understanding with practical lab activity. It creates the technical context needed before the programming-focused MPI, OpenMP and CUDA units.
This module introduces the parallel-computing fundamentals that underpin the later programming units. Learners use the theory session to understand the principles represented by the module and the hands-on session to reinforce them in practice. The unit provides a bridge from HPC architecture into distributed-memory, shared-memory and GPU computing workflows.
This module develops the source-defined area of distributed-memory programming with MPI. Learners combine a theory session with a hands-on session to connect the programming model with practical activity. The module builds directly on parallel-computing fundamentals and prepares learners to compare distributed-memory work with the shared-memory approach introduced in the following unit.
This module focuses on shared-memory programming with OpenMP as specified in the curriculum. The theory session establishes the relevant concepts and the hands-on session reinforces them through practical activity. Positioned after the MPI unit, it helps learners distinguish another parallel-programming approach before the course advances to GPU computing with CUDA.
This module introduces GPU computing with CUDA within the approved HPC sequence. Learners use the theory session to understand the role of GPU acceleration and the hands-on session to reinforce the source-defined workflow. The unit extends the course from CPU-oriented parallel programming into accelerated computing before the curriculum shifts toward local HPC operations.
This module connects HPC programming with the local operations named in the source: SLURM, storage, containers and a Proxmox lab. The theory session establishes operational context, while the hands-on session reinforces the workflow through practical activity. It broadens the learning path from programming models to the environment used to organize and support HPC work.
The final module brings the eight-unit pathway together through HPC performance optimization and capstone workflows. Learners use the theory session to examine optimization considerations and the hands-on session to integrate ideas from architecture, parallel programming, GPU computing and local operations. The module provides a source-aligned conclusion without introducing additional topics beyond the approved curriculum.
The project submission process helps learners apply Generative AI concepts in a practical and structured way. Therefore, participants complete project work to demonstrate their understanding, originality, and professional application.
First, explore the project topics available in the LMS. Review the project description, learning outcomes, and required skills before selecting your topic.
If required, ask your guide or mentor for support. After that, finalize your topic and begin your project work.
Once your project report is complete, follow the project submission guidelines for formatting, font, spacing, citations, and originality.
Your report will go through a plagiarism check. Therefore, keep the work original, properly structured, and clearly written.
Finally, upload your final PDF report and any supporting files to the LMS.
After submission, your project is evaluated by an organization mentor and an internal faculty supervisor.
The evaluation focuses on report quality, depth of understanding, concept application, problem-solving skills, professional behaviour, and timely submission. In some cases, a viva or presentation may also be required.
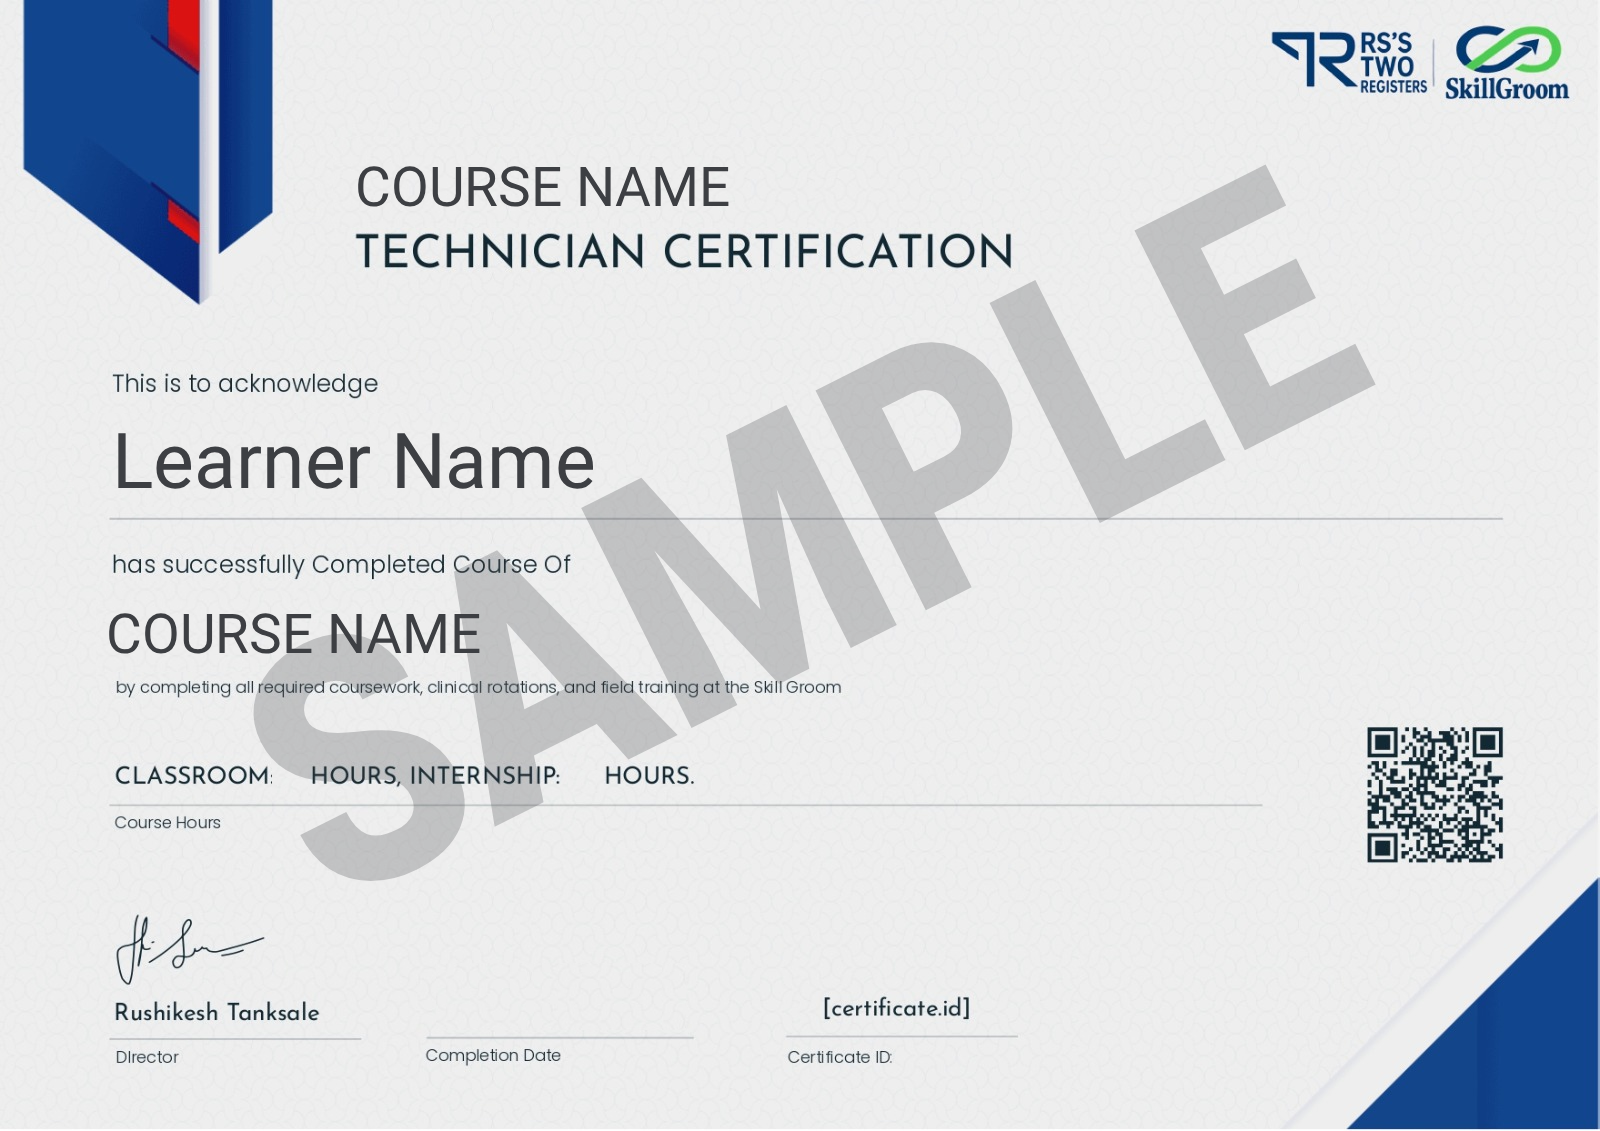
Credits may be awarded as per applicable UGC NEP 2020 guidelines. In addition, your internship certificate will be issued after report approval, evaluation completion, and uploading of the required organization certificate.
Thereafter, learners can download the internship completion certificate directly from the LMS.